Aravindkumar K S
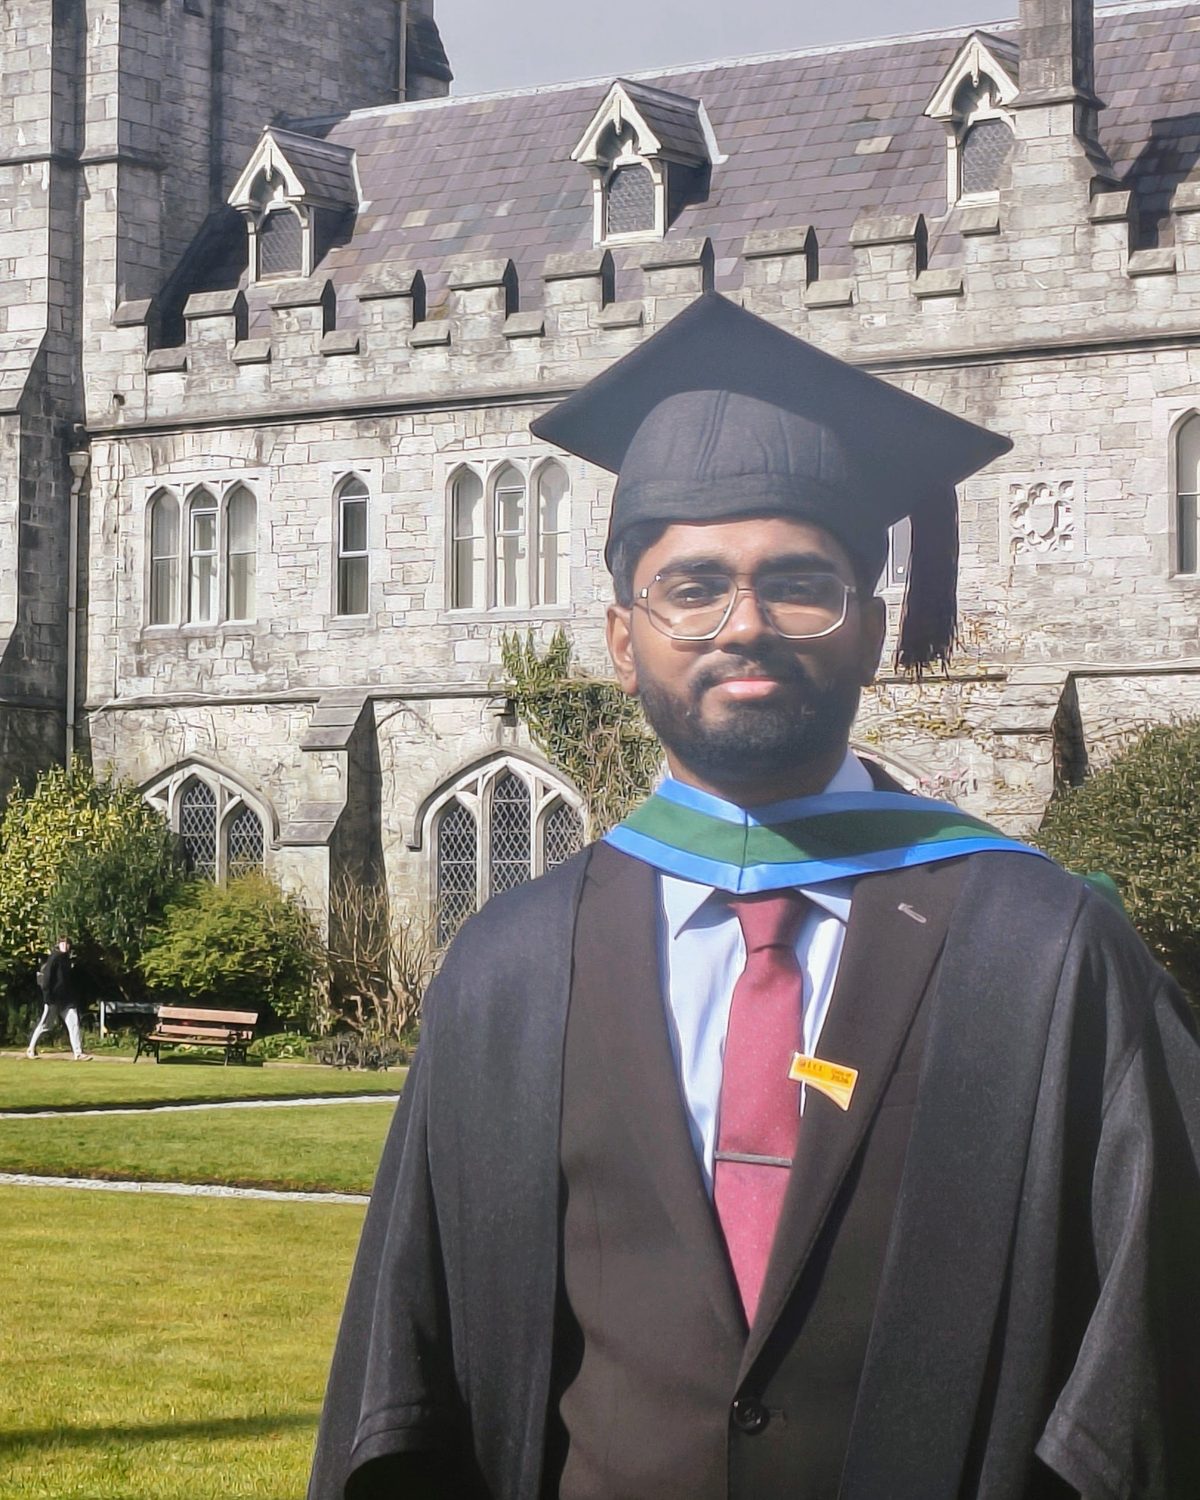
Portrait of Aravindkumar K S

Cork, Ireland

Aravindkumar K S

AI engineer. Retrieval, LLM tooling, and the evaluation that keeps them honest.

  • AWS Certified ML Engineer – Associate
  • MSc, First Class Honours, UCC
  • Stamp 1G, eligible to work in Ireland
~30%
less policy-document processing timeInsurance RAG assistant at LTIMindtree
95%+
extraction accuracy20+ vendor document formats into a Neo4j knowledge graph
~3x
inference throughputSelf-hosted vLLM service vs a naive Hugging Face pipeline
16%
fewer parametersMSc research, FC-KAN accuracy matched, 21–23% faster training

About

Portrait of Aravindkumar K S

I'm an AI/ML engineer in Cork. Most of my work so far has been on retrieval systems and the tooling around LLMs: getting the right documents in front of the model, checking what comes out, and keeping it running.

I spent two years at LTIMindtree in Bengaluru, starting as a graduate engineer trainee. Generative AI took off just after I joined, so I learned a lot of it on the job: a production RAG assistant for insurance documents, the extraction pipeline and knowledge graph behind it, and Studio, the team's model portal, with the gateway and guardrails around it, all running on AWS.

In 2024 I moved to Ireland for an MSc in Mathematical Modelling and Machine Learning at UCC, because I wanted to understand the models better than I did. My research looked at making Kolmogorov–Arnold Networks smaller and faster to train.

Since finishing, I've built projects of my own (an agentic RAG assistant, a self-hosted vLLM inference service and an LLM evaluation harness), earned the AWS ML Engineer certification, completed LangChain and Anthropic MCP courses, and mentored first-time programmers at Django Girls Cork. I also work with coding agents such as Claude Code, including MCP servers, skills, hooks and subagents.

Experience

Independent Projects & Professional Development

Cork, Ireland

AI/ML Engineering Oct 2025 – Present

  • Designed and built production-grade AI systems to deepen applied LLM and MLOps expertise — an agentic RAG assistant, a self-hosted vLLM inference service, and a CI-integrated LLM evaluation harness (detailed under Projects).
  • Earned the AWS Certified Machine Learning Engineer – Associate certification and completed LangChain and Anthropic Model Context Protocol (MCP) courses, formalizing cloud ML and agent-tooling skills.
  • Mentored first-time programmers as a Django Girls volunteer and stayed engaged with the AI engineering community while pursuing full-time AI Engineer / Forward Deployed Engineer / Software Engineer roles
  • LangChain
  • vLLM
  • RAGAS
  • DeepEval
  • Langfuse
  • AWS
  • Model Context Protocol (MCP)

LTIMindtree (now LTM)

Bengaluru, India

Senior Consultant – Package ImplementationInsurance R&D Oct 2022 – Aug 2024

I worked on GenAI projects in insurance R&D, from first proof of concept to production.

  • Led the proof-of-concept and co-built a production insurance RAG assistant (LangChain, FastAPI), cutting bulk policy-document processing time ~30% including manual extraction-quality review, at a 4–5s p95 time-to-first-token.
  • Owned an event-driven extraction pipeline (Textract, S3, SQS with dead-letter queues, Lambda consumers, Step Functions) parsing 20+ vendor formats into a Neo4j knowledge-graph insurance ontology at 95%+ accuracy, auto-quarantining malformed inputs.
  • Co-built Studio, the team's central model portal (React, FastAPI) providing model access, management and governance — rate limiting, PII redaction, content moderation, domain gating and application-based access control.
  • Contributed to evaluation baselines using a RAGAS harness and Langfuse tracing, wiring context-relevance and faithfulness checks into CI as release gates to catch retrieval regressions.
  • Built ingestion, chunking and embedding pipelines feeding Chroma-based hybrid retrieval (dense vectors + BM25 via Reciprocal Rank Fusion), sustaining bulk re-index throughput through SQS-buffered Lambda workers, with versions tracked in MLflow.
  • Independently built a VS Code extension on Studio bringing LLM chat, code generation, review and editing, model switching and history into the IDE for the engineering team.
  • Contributed to the LLM inference gateway behind Studio (FastAPI edge, internal gRPC/protobuf), adding a Redis semantic cache that cut redundant LLM calls ~5% and helping enforce GDPR-compliant PII handling.
  • Contributed to migrating infrastructure-as-code from CloudFormation to Terraform, building reusable ECS/ECR/Lambda/S3 modules with least-privilege IAM and encryption, and cutting AWS spend ~10% through ECS right-sizing and autoscaling.
  • Contributed to containerized blue-green ECS releases via GitHub Actions and CodeBuild, with SonarQube and Trivy security gates enabling low-risk deployments across Dev, Test and Prod.
  • LangChain
  • FastAPI
  • RAG
  • Hybrid retrieval (BM25 + RRF)
  • Chroma
  • Neo4j
  • Knowledge graphs
  • Amazon Textract
  • AWS Lambda
  • S3
  • SQS
  • Step Functions
  • ECS
  • ECR
  • MLflow
  • RAGAS
  • Langfuse
  • React
  • gRPC/protobuf
  • Redis
  • PII redaction
  • Terraform
  • CloudFormation
  • GitHub Actions
  • CodeBuild
  • SonarQube
  • Trivy

LTIMindtree (now LTM)

Bengaluru, India

Graduate Engineer Trainee Jul 2022 – Oct 2022

  • Built Angular tooling for configuring data-pipeline scan jobs and reviewing classification results and privacy insights, giving analysts a self-serve interface to manage scans without engineering support.
  • Designed PostgreSQL data models with Spring Boot and Hibernate ORM for data sources, job-run history and classified elements, supporting reliable tracking of scan lineage across runs.
  • Wrote SQL queries and aggregations powering data-discovery and coverage-monitoring dashboards, giving stakeholders visibility into classification coverage across data sources.
  • Delivered maintainable features in sprint increments through Agile cycles and peer reviews, improving code quality and reducing review turnaround.
  • Java
  • Spring Boot
  • Hibernate
  • Angular
  • PostgreSQL
  • SQL
  • Agile

Projects & Research

Agentic RAG & Conversational Knowledge Assistant

An assistant that decides for itself whether to search documents, query a database or look something up on the web.

  • Python
  • LangChain
  • Tool calling
  • OpenAI
  • Pinecone
  • Hybrid search
  • Redis
  • Pydantic
  • FastAPI
  • Gradio
  • RAGAS
Problem
Most chatbots answer every question the same way, so they guess when the answer lives in a database or online.
Built
A LangChain tool-calling agent that routes each query across vector search, SQL lookup and web search, returning Pydantic-validated structured outputs over multi-turn, Redis-backed conversation state.
Hard part
Retrieval quality. I tuned chunking (semantic vs fixed-size, overlap) and hybrid search using OpenAI embeddings and Pinecone, and diagnosed retrieval failures like missed context through RAGAS context-recall analysis.
Result
An LLM-based response classification and filtering guardrail layer catches ungrounded or irrelevant responses before they're returned, improving answer grounding and quality.

LLM Evaluation Harness

A reusable test suite that scores models and prompts, and blocks a merge when the scores drop.

  • Python
  • pytest
  • RAGAS
  • DeepEval
  • Langfuse
  • OpenAI/Anthropic APIs
  • GitHub Actions
Problem
A prompt or model change can make answers worse without anyone noticing until users do.
Built
A reusable harness that scores models and prompts on curated datasets across accuracy, faithfulness, relevance and latency, with pluggable metrics and provider-agnostic adapters.
Hard part
Trusting the judge. I implemented LLM-as-judge and reference-based scoring with RAGAS and DeepEval, and calibrated the judge prompts against human labels to improve metric–human agreement.
Result
The harness runs in CI as a regression gate via GitHub Actions, blocking merges on score drops and logging per-run traces to Langfuse for diagnosis.

Optimized LLM Inference Serving

A self-hosted LLM service tuned to serve more requests, faster, on a single GPU.

  • Python
  • vLLM
  • FastAPI
  • PyTorch
  • Hugging Face Transformers
  • Docker
  • Prometheus
Problem
A naive Hugging Face pipeline makes poor use of the GPU: throughput is low and larger models don't fit.
Built
A self-hosted inference service with vLLM behind a FastAPI gateway, using continuous batching and PagedAttention.
Hard part
GPU memory and latency. I applied INT8/AWQ quantization and KV-cache tuning, then benchmarked throughput, latency percentiles and tokens/sec under concurrent load.
Result
~3x throughput over a naive Hugging Face pipeline, ~50% less GPU memory and ~40% lower p95 latency, enough to fit larger models on a single GPU. Prometheus metrics drive autoscaling and catch performance regressions.

MSc Research: Wendland's CSRBF in Kolmogorov–Arnold Networks (KAN)

A smaller, faster version of a newer neural network architecture. Research project at UCC, under Dr. Andreas Amann.

  • PyTorch
  • Kolmogorov–Arnold Networks
  • Radial basis functions
  • Regularization

Repo

Problem
Kolmogorov–Arnold Networks learn their own activation functions, but they're expensive to train.
Built
KAN alternatives in PyTorch that replace B-spline and Gaussian edge activations with compactly supported Wendland radial basis functions (a lighter building block that only switches on locally), with trainable centers and support radii.
Hard part
Keeping trainable radii stable, which I did with inverse-L2 regularization, and quantifying the sparsity–accuracy trade-off.
Result
Compared across six baselines.
Tab. 1 — benchmarks
BenchmarkResult
MNIST vs FC-KAN97.6% vs 97.7% accuracy, 16% fewer parameters, 21–23% faster training
Fashion-MNIST86.7% → 88.7% accuracy
Activation density vs Fast-KAN (fixed radii)~25% vs 88%

More projects

Serverless Observability on AWS

A small serverless service where I break things on purpose to check the monitoring catches it.

  • Terraform
  • AWS Lambda
  • API Gateway
  • SQS
  • DynamoDB
  • CloudWatch
  • SNS
  • KMS
  • IAM
  • Python
Problem
Serverless apps are easy to deploy and hard to debug when they fail at 3 a.m.
Built
A modular Terraform stack for a serverless order service with a sync path (API Gateway → Lambda → DynamoDB) and an async path (SQS → worker Lambda + DLQ), on an S3-locked remote backend.
Hard part
Making failures visible, through structured JSON logging, metric filters and EMF custom metrics, with saved Logs Insights queries for latency percentiles, cold starts and request tracing.
Result
Fault injection (error rate, latency, poison messages) reproduces failures and validates metrics and alerting end to end. Least-privilege IAM, PII masking via CloudWatch Logs data protection, and KMS-encrypted SNS alerting with scoped key and topic policies keep it secure.

Predictive Modeling for Customer Churn

A churn model that also explains why customers leave.

  • Python
  • pandas
  • scikit-learn
  • XGBoost
  • Optuna
  • SHAP
  • MLflow
Problem
Knowing who might churn isn't enough; a retention team also needs to know why.
Built
An end-to-end churn-prediction pipeline on 50k+ customer records, with behavioral and temporal features. I trained and compared logistic regression, random forest and XGBoost, tuned hyperparameters with Optuna and tracked experiments in MLflow.
Hard part
Class imbalance, handled with SMOTE and stratified cross-validation.
Result
0.89 ROC-AUC. SHAP surfaced the top churn drivers, which I turned into retention recommendations for non-technical stakeholders.

Education & credentials

Education
DegreeInstitutionDatesHighlight
MSc Mathematical Modelling & Machine LearningUniversity College Cork, Cork, IrelandSep 2024 – Sep 2025
  • First Class Honours (1.1)
  • Coursework: Deep Learning (ANN, RNN, VAE, Transformers, RL), Statistical Methods (Data Analysis, EDA, Regression, Classification, Unsupervised Models)
BE Mechanical EngineeringKumaraguru College of Technology, Coimbatore, IndiaJul 2018 – Jun 2022
  • First Class with Distinction (8.8/10.0 CGPA)
  • Publication: “Design Optimization of Grids in Grid Fins for Spacecrafts”, International Journal of Vehicle Structures and Systems (IJVSS), 2022
Certifications
CertificationIssuerDate
AWS Certified Machine Learning Engineer – AssociateAmazon Web ServicesSep 2026
Foundation: Introduction to LangChain – PythonLangChainMay 2026
Model Context Protocol: Advanced TopicsAnthropicApr 2026
Introduction to Model Context ProtocolAnthropicMar 2026
Awards
  • Shooting Star Award, LTIMindtree, Bengaluru (Apr – Jun 2024): recognised as a top team contributor for consistently delivering high-impact features on the Studio platform during Q1.
  • Rising Star Award, LTIMindtree, Bengaluru (Sep 2023): Young Achiever award for exemplary contribution in my first year at the company.

CommunityVolunteer Mentor, Django Girls Cork (Sep 2026). Coached a group of 3 first-time programmers through building and deploying a full Django blog application to PythonAnywhere in a single-day workshop.

Contact

I'm based in Cork and open to AI Engineer, Forward Deployed Engineer and Software Engineer roles in Ireland. LinkedIn is the best place to reach me, and my code is on GitHub.

Cork, Ireland · Stamp 1G, eligible to work in Ireland · Hybrid, onsite or remote within Ireland · English, Tamil

LinkedIn GitHub CV (PDF)